

How to Use an AI Image Describer: Real Outputs From All Seven Modes
Need alt text, captions or the words out of a photo? I ran all seven modes of Vormly's describer on real images. Here's what each one got right, what it got wrong, and which one I'd reach for.
LPLeo PanFounder, VormlySay a batch of product photos goes live tomorrow, and every one of them still needs alt text, the short description a screen reader reads out loud. The first few get real care. By the tenth, they all start to sound alike.
An AI tool can take the first draft off your hands and write it in a few seconds. Two decisions stay with you, though: what kind of description the job calls for, and which lines to check before anything goes live. I wanted to see where those checks actually matter, so I ran all seven modes of the Vormly AI image describer on real images and kept every answer, the wrong ones too.
TL;DR
For alt text or a caption, start with Describe Briefly. If you need every detail written down, use Describe in Detail. For the words printed in an image, use Extract Text, and for one specific fact, use Ask a Question. Whichever you pick, read the answer once before you publish it. In my tests the describer was dependable about what's actually in a picture. It slipped when it guessed, when it counted lots of similar things, and once when it listed a single object as two.
What an image describer is good for
Think of a folder of images that all need words: a caption for every post, a description for every product, the text off a stack of scanned receipts. Doing it by hand takes ages, and the last few never get the care the first ones did.
A describer does the writing part. You upload a picture, an AI that can read images looks at it, and you get plain text back. What kind of text depends on what you ask for: a short description, a long one, a list of what's in the picture, the words printed in it, or the answer to a question.
Where it earns its keep:
- Alt text and captions. Someone using a screen reader hears a short description in place of the image. The web's accessibility rules, in WCAG Success Criterion 1.1.1 (opens in a new tab), ask for one on every image that matters to the page.
- Making a big image library searchable. Once every product photo or archive picture has a description, you can find it by typing a few words.
- Getting text out of images. Signs, screenshots, posters and scans become text you can paste, so you don't have to retype them.
- Quick questions. Ask something specific, like what a label says, and get a direct answer.
How I tested
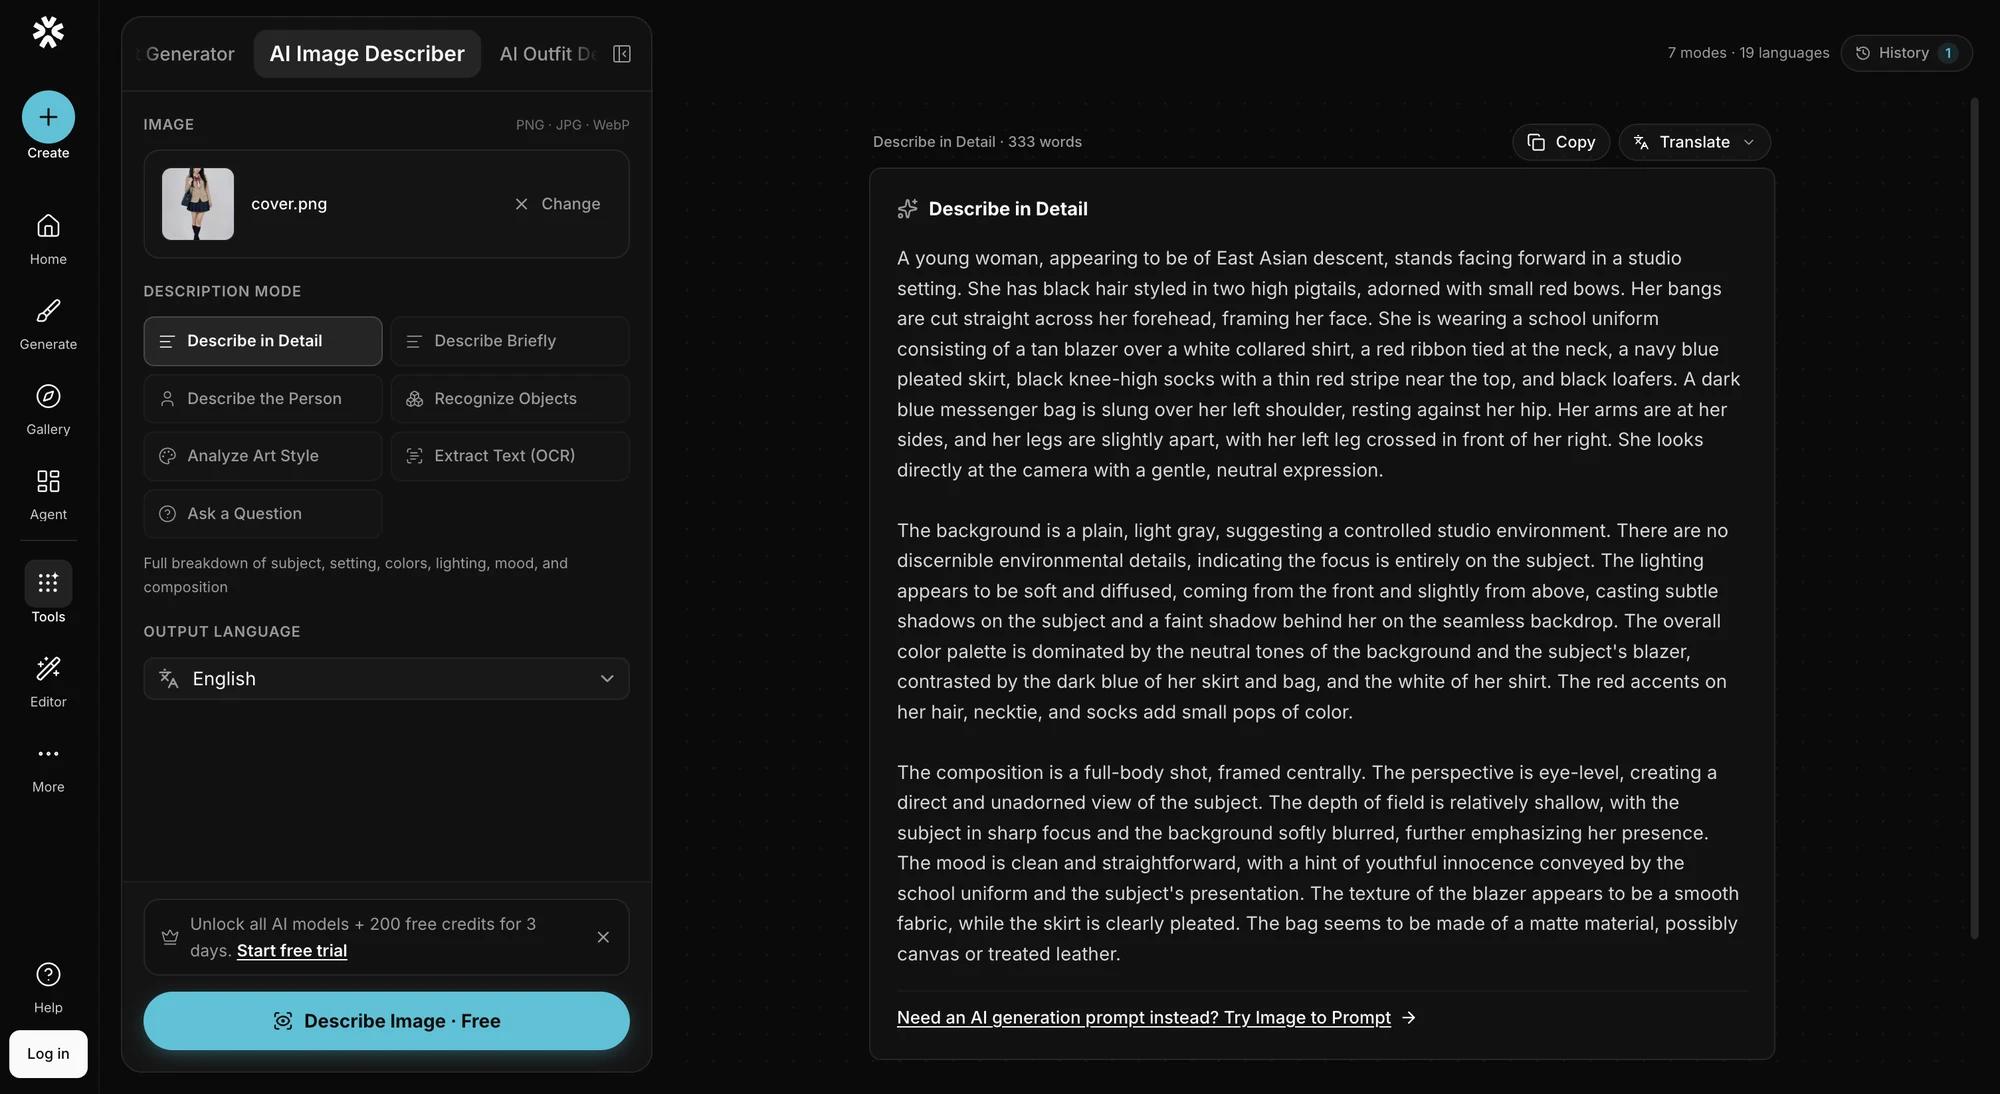
That's the describer. You upload an image on the left, choose a mode and the language you want the answer in, and the result shows up on the right. It takes PNG, JPG and WebP files up to 10 MB. I ran these tests when it had seven modes; Alt Text, Caption and Product Description have been added since, and they aren't covered below. You can run 8 descriptions a day without an account, and once you sign in each one costs 1 credit.
For each mode I picked an image from the Vormly gallery that suits what the mode is for, and I ran them all on September 15, 2026. The tool shrinks every image so its longest side is 1,024 pixels before the AI sees it, and my test images went through that same step, so what you see below is what you'd get. The AI phrases things a little differently on every run, so read the mistakes below as the kinds of slips to look out for, not a complete list.
What's actually reading your image
All seven modes run on the same model, Google's Gemini 2.5 Flash-Lite (opens in a new tab). It takes in text, images, video, audio and PDFs and answers in text, and Google designed it for simple jobs that need to be fast and cheap at large scale, like sorting things into groups or pulling out basic information. The describer uses the stable version released on July 22, 2025, and Google's Gemini deprecation schedule (opens in a new tab) doesn't list a date for switching it off.
Knowing that made the results easier to read. The seven modes aren't seven different AIs. Each one sends your picture to the same model with different instructions. And that model is strongest on plain facts: which objects are there, what the text says, how many of something there are when there are only a few. It gets shakier once it starts guessing, like the time of day in a photo or which art movement a painting leans toward.
Which mode to use for which job
| What you need | Mode | What you get | Check before you use it |
|---|---|---|---|
| A full written record for a catalogue or archive | Describe in Detail | 150 to 300 words on what's there, the setting, the light and the mood | Sentences where it guesses instead of describing |
| Alt text for a photo | Describe Briefly | One or two sentences, never more than 40 words | Trim it to what your page needs |
| Notes on a portrait | Describe the Person | Looks, clothes and pose, but never who the person is | The age is only an estimate |
| A list of everything in a product shot or scene | Recognize Objects | One item per line, in groups | One item listed as two |
| A name for a visual style | Analyze Art Style | The style, medium, colors and artists it brings to mind | Claims about how it was made, and answers that contradict themselves |
| The words inside an image | Extract Text | The text copied exactly, with a note on where each piece sits | The notes about where text sits, and shapes listed with no text |
| One specific fact | Ask a Question | An answer based only on what it can see | Counts of lots of similar things |
Describe in Detail: solid on facts, shaky on guesses
This is the mode for when a caption won't do, say you're building a catalogue or an archive and each image needs a proper written record.
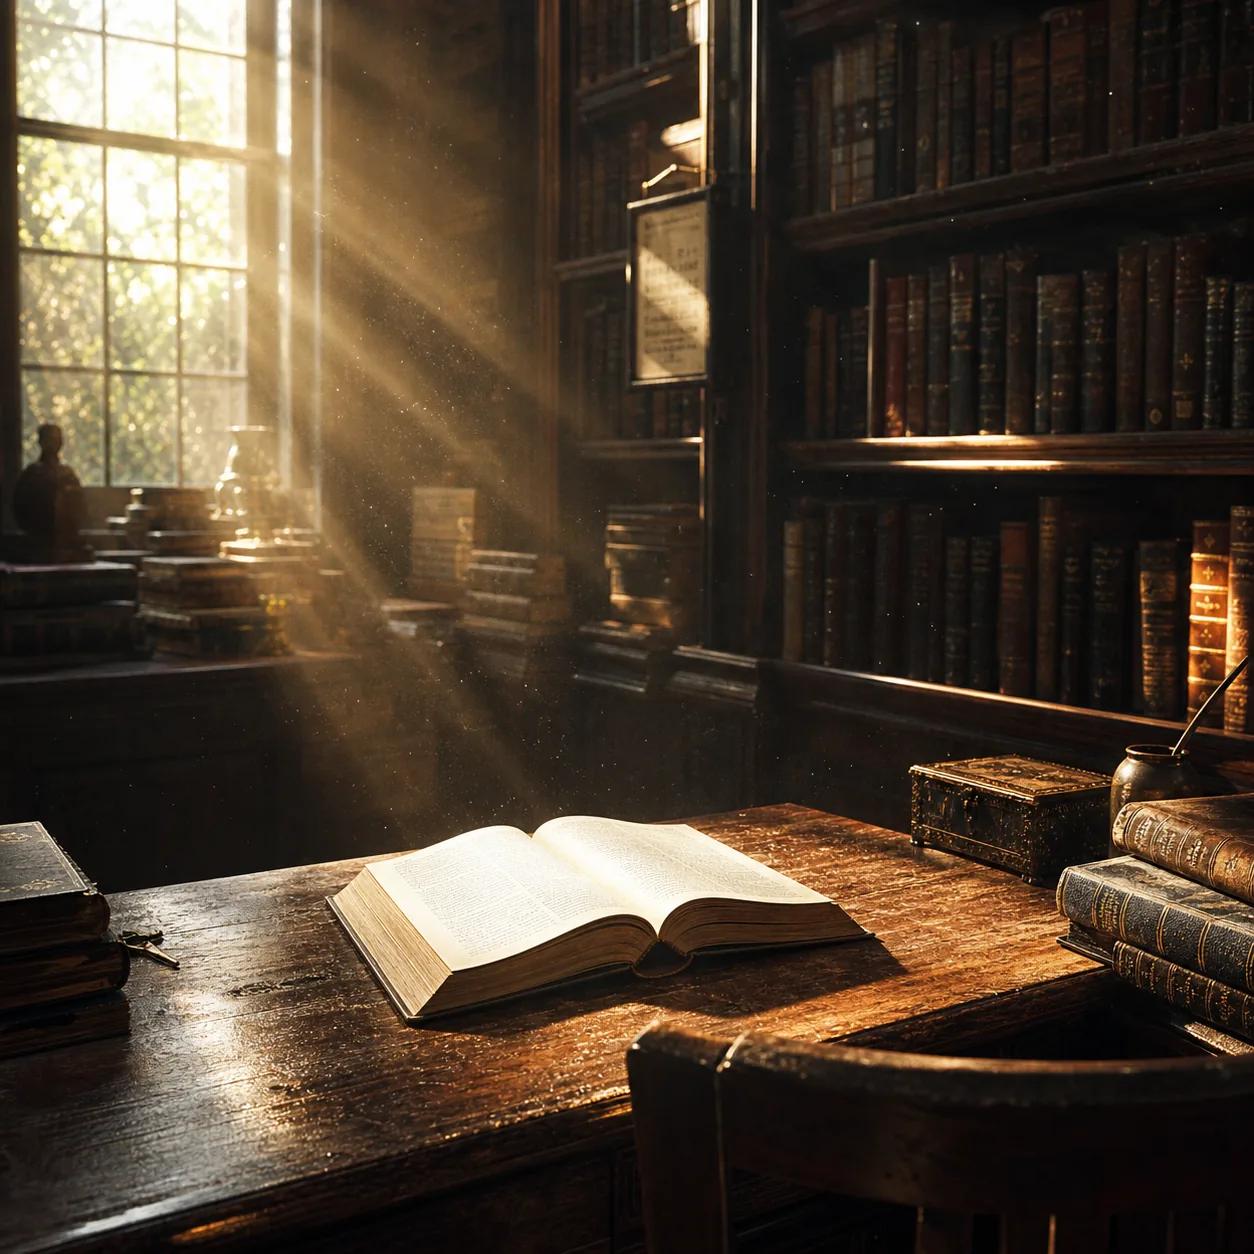
Output · Describe in Detail309 words · first two of three paragraphs
It caught almost everything that's really in the picture: the open book, the stack of old books with a key next to it, the box, the inkwell and quill, the window, the dust hanging in the light, even the low camera angle that puts you in the chair at the desk.
The problems are all in the sentences where it guesses, and those read just as confidently as the rest:
- It can't make up its mind about the book. It says the open book suggests it "is currently being read or has just been closed." A book lying open wasn't just closed.
- It guesses the time of day. From the light alone it decides the scene is "likely late morning or early afternoon." Nothing in the picture tells you that.
My verdict
I'd use Describe in Detail as a first draft for catalogues and research. Keep what it says about what's in the picture, and check or cut any sentence about what the scene means or when it happened.
Describe Briefly: where I'd start for alt text
This is the one for that batch of product photos, or any image that needs a caption or alt text.
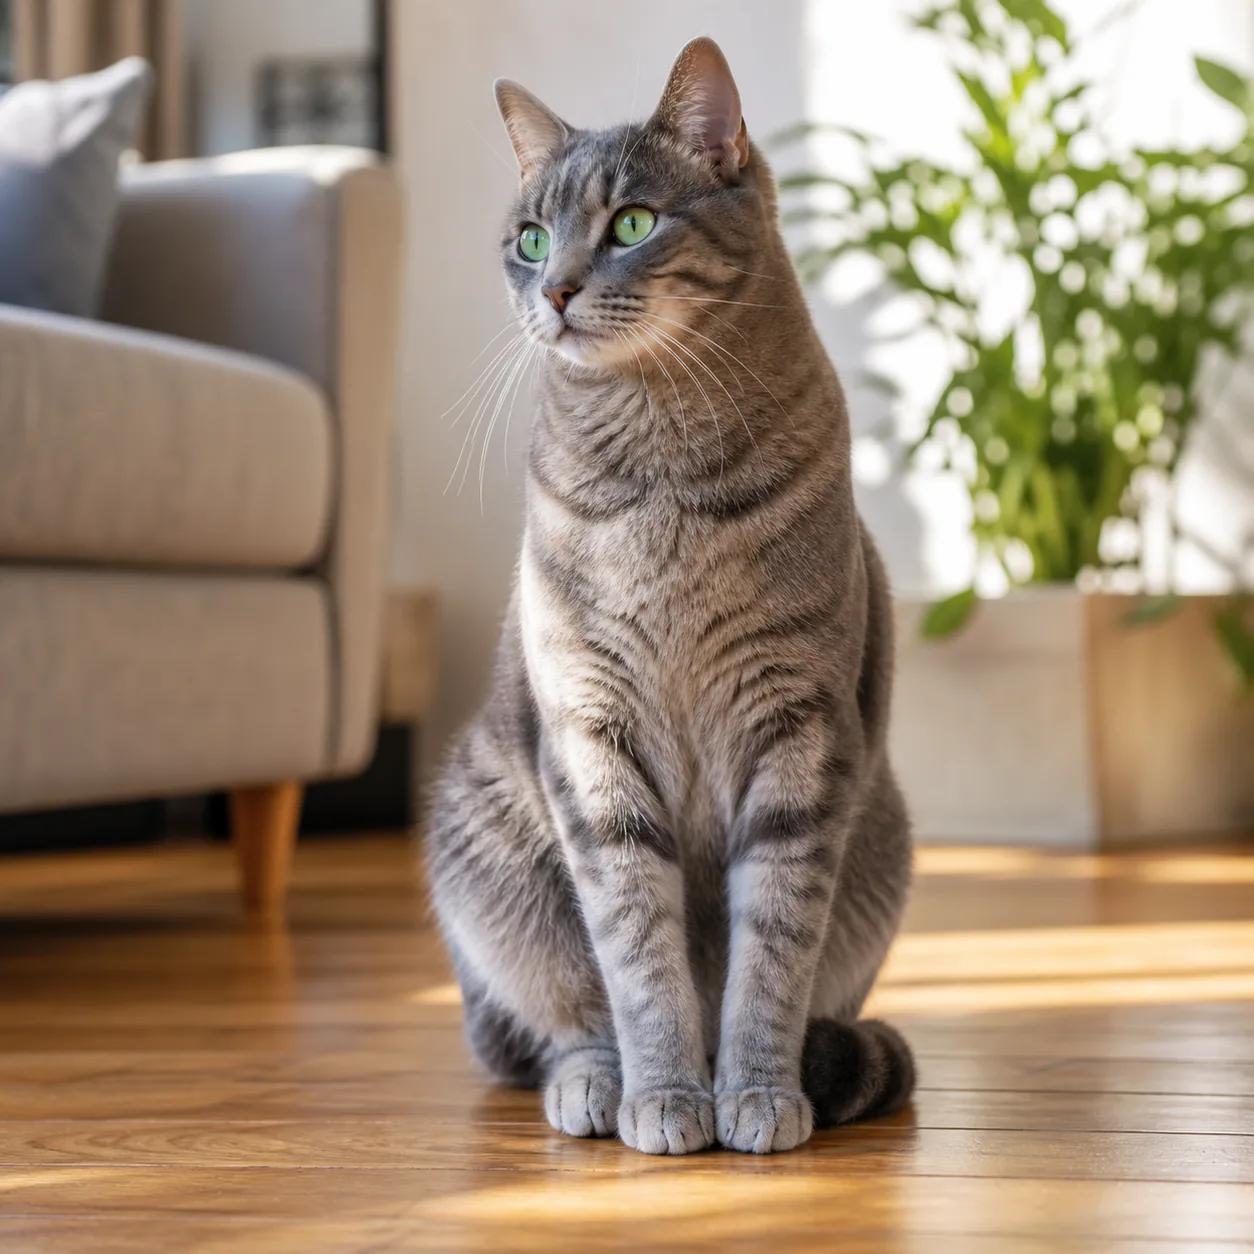
Output · Describe Briefly25 words
The limit is 40 words and it used 25. It says what the photo is, the first detail you'd notice (the green eyes), where the cat is sitting and what's behind it. I couldn't find a wrong word in it.
I'd still treat it as a draft. If the page is about the cat, the sofa and the plant can go. And if the photo already has a caption saying the same thing, you can leave the alt text empty. The alt text section near the end explains when that applies.
Describe the Person: what someone looks like, never who they are
Reach for this one when portraits or team photos need descriptions, for a website or a photo library.
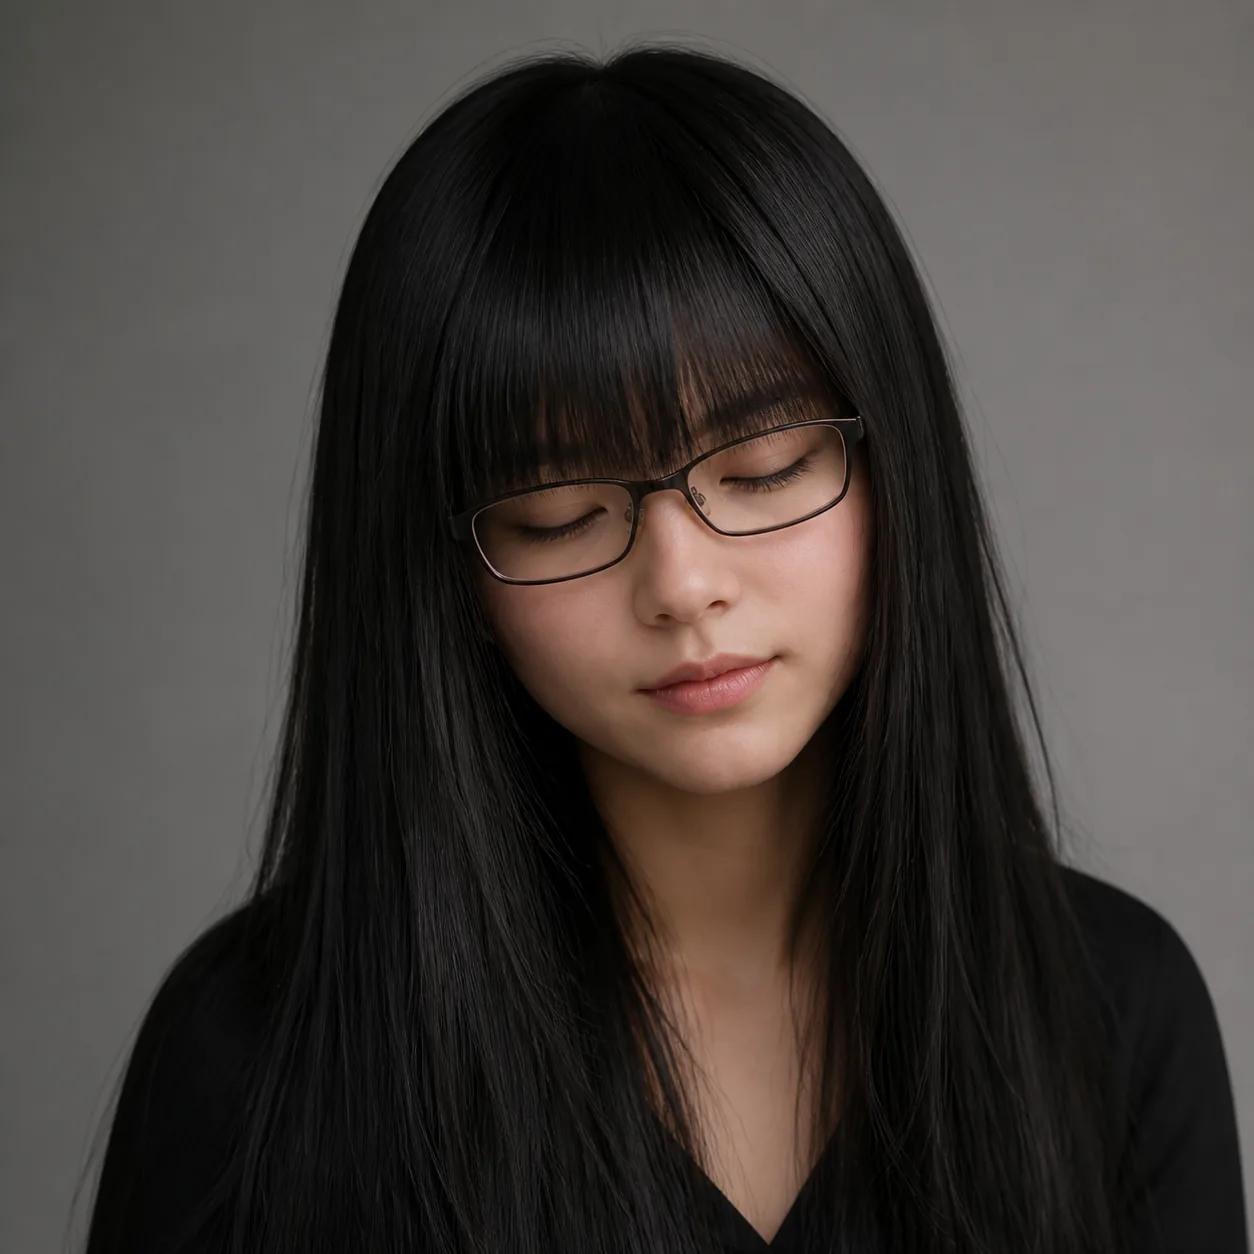
Output · Describe the Person121 words
It kept to what you can see: hair, glasses, expression, the tilt of the head, the clothes and how the shot is framed. All of it matched the photo. The mode is built to never say who a person is, even if they look like someone famous, and when there's nobody in the picture it says so and describes what's there instead.
The one line I'd be careful with is the age: "likely in her late teens or early twenties." That's a guess, and I wouldn't publish a guess like that about a real person.
Recognize Objects: a tidy list, with one item counted twice
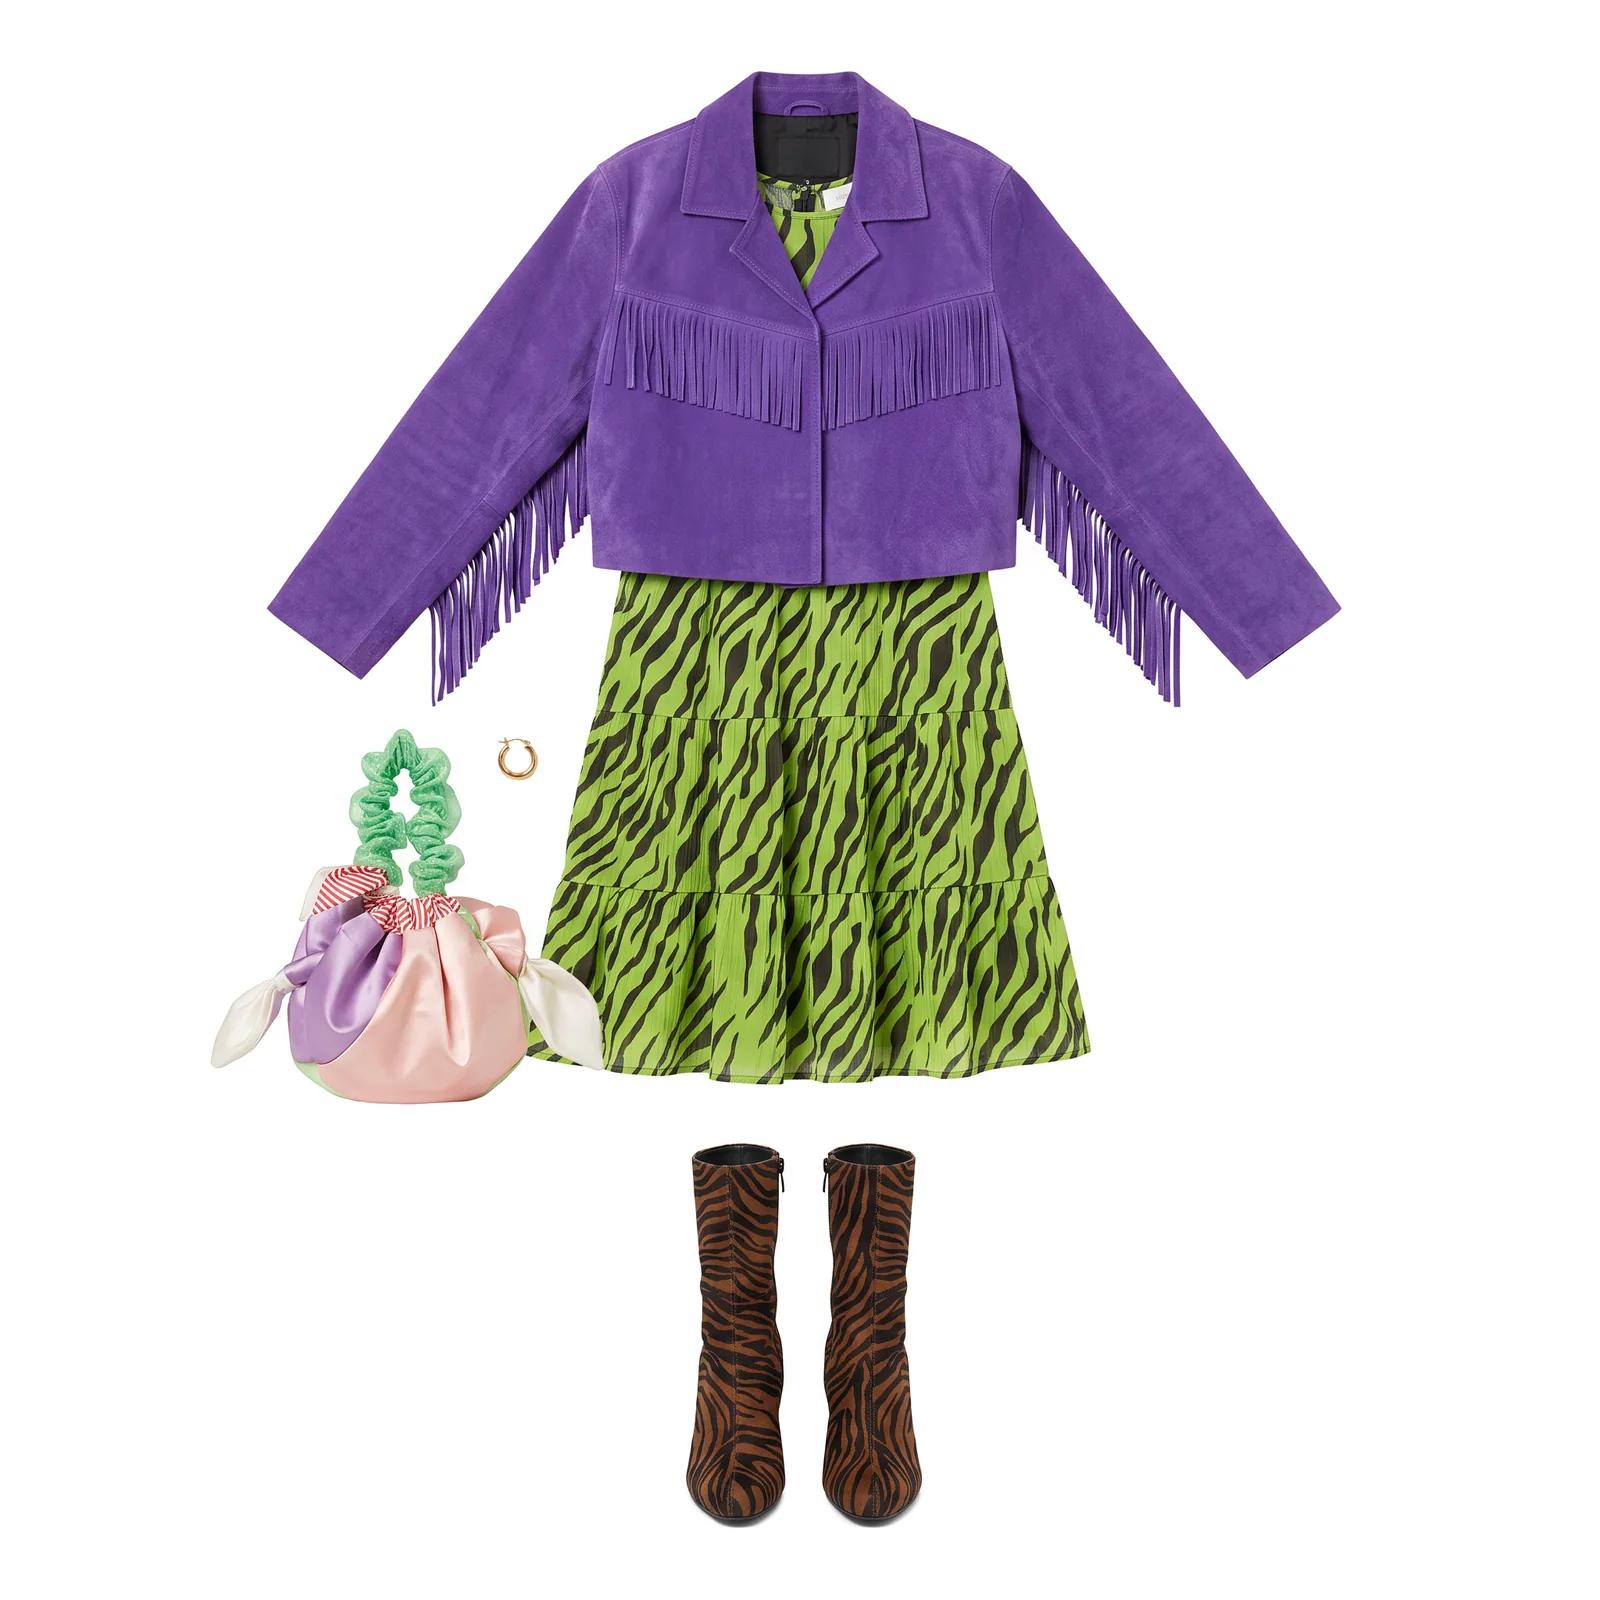
If you sell clothes online, this is the mode that turns each product shot into a list of what's in it.
Output · Recognize Objects72 words
The list is tidy, grouped the way a shop would group it, and it pastes straight into a spreadsheet. It even caught the small black tag inside the jacket collar.
It got one thing wrong. The "Green scrunchie" is really the bag's ruffled handle, so the list has one more item than the photo. This mode is good at noticing things, and less sure about where one object stops and the next one starts.
For clothes specifically, the outfit describer goes a step further and covers each garment, what it's made of, and the overall style.
Describe an outfit in detailDescribe any outfit — garments, fabrics, hair & the style it belongs toAnalyze Art Style: good at naming a look, not at how it was made
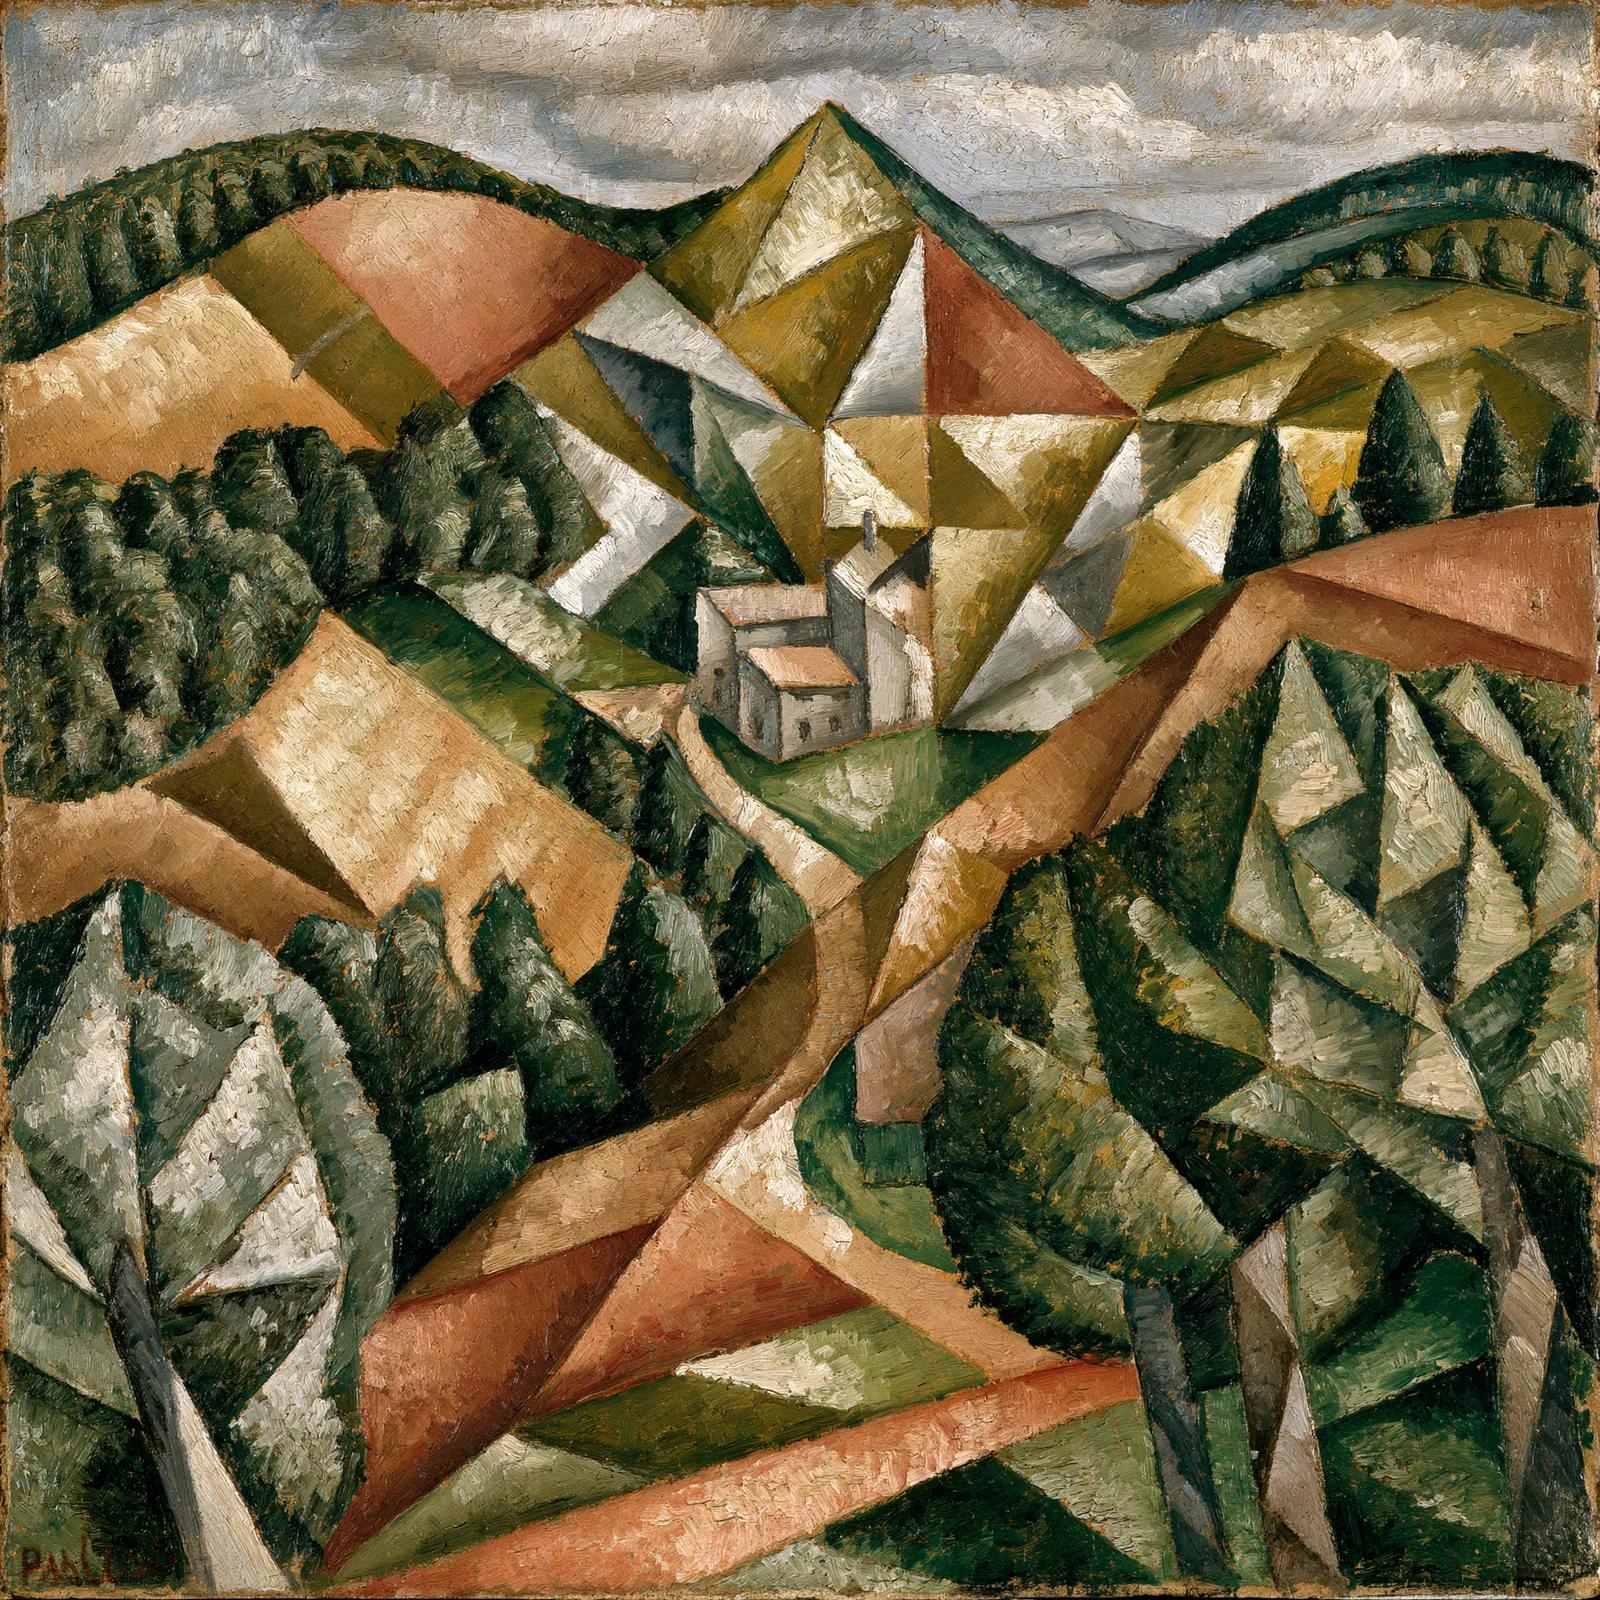
Ever found an image you love and couldn't put a name to its style? This mode gives you the words, whether you're briefing a designer or hunting for more images like it.
Output · Analyze Art Style228 words · first and last of four paragraphs, bold formatting removed
The vocabulary is the part worth having. It spotted Cubism straight away, brought up Pablo Picasso and Georges Braque, and explained how the picture is broken into flat, angular shapes. Those are exactly the words you need when you're describing a look to someone else.
Two things I wouldn't trust. It calls the picture an oil painting, "evident from the visible texture," when it's actually an AI image made to look painted. And it links the style to Orphism because of the "vibrant, faceted planes and a focus on color," then a paragraph later calls the palette "earthy and subdued." So I take anything it says about how a picture was made as a guess, and I read the whole answer for places where it disagrees with itself.
Extract Text: the words come out right, the notes about where don't
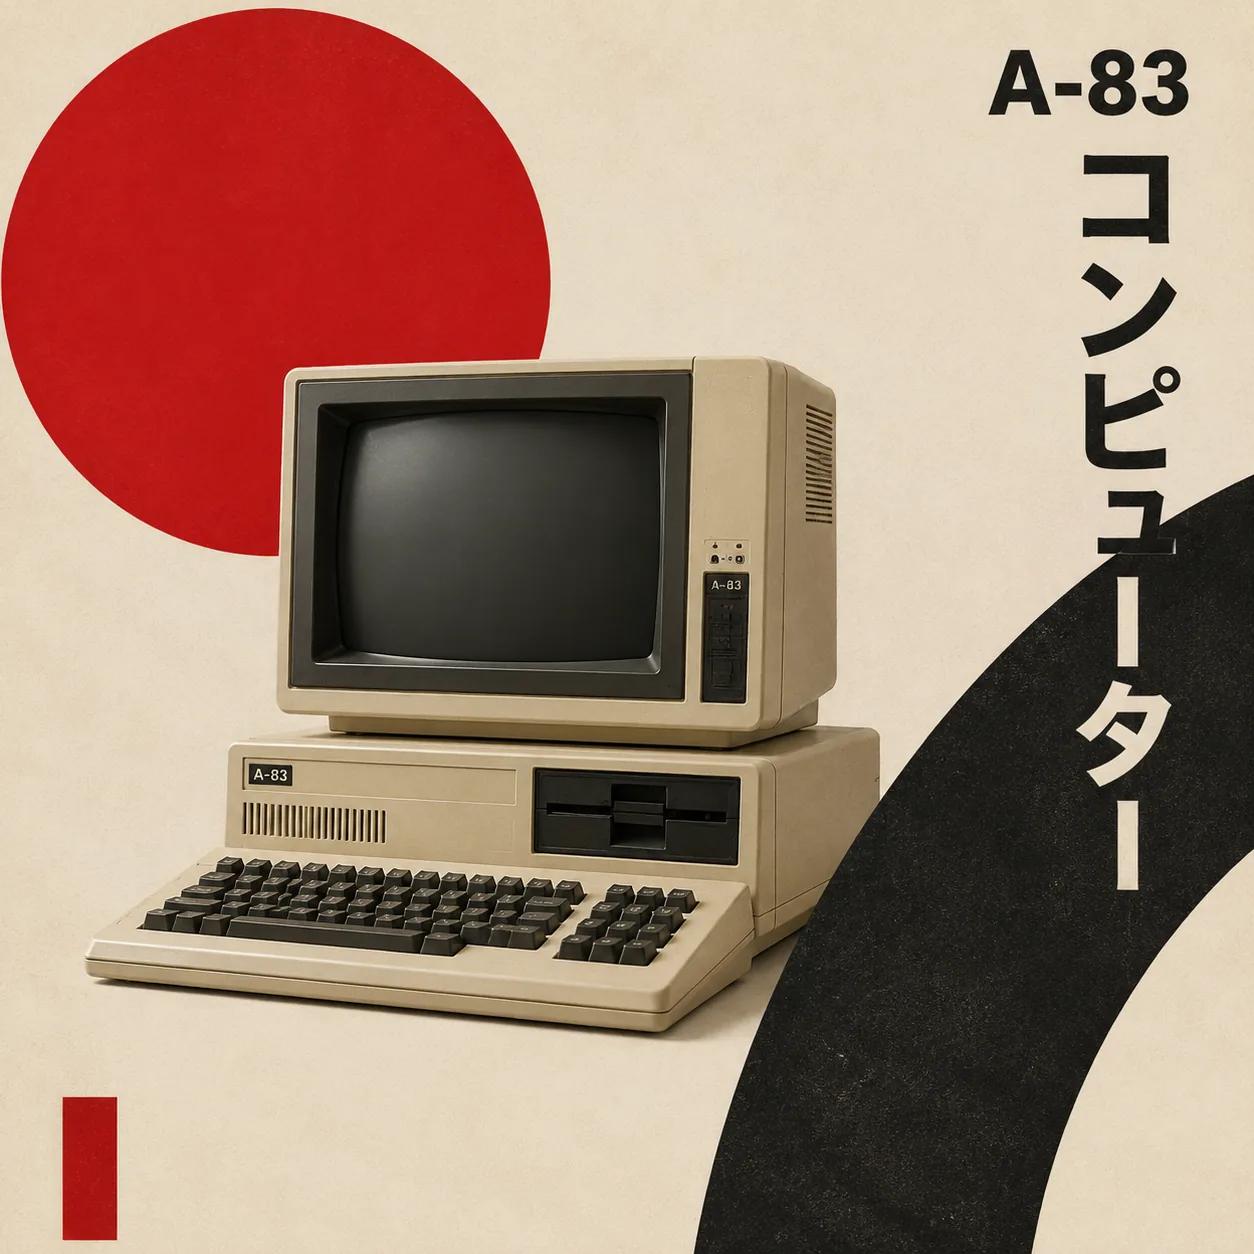
Retyping the words from a sign, a screenshot or a poster is slow, and it's easy to slip up. This mode copies them out for you.
Output · Extract Text24 words
Every word was right: "A-83" all three times it appears, and コンピューター left in Japanese rather than translated. The only slip is the last line, a red rectangle listed even though there's no text in it.
The output language setting behaves a bit differently in this mode. When I switched it to Spanish, the notes about where each piece of text sits came back in Spanish, and the Japanese stayed Japanese. If you're copying text rather than translating it, that's exactly what you want:
Output · Extract Textoutput language Spanish
The Spanish run also showed where this mode is weak. It listed the label on the computer's base twice and put the monitor's label at the bottom left, which is wrong. I'd trust the words. I wouldn't trust the notes about where they are.
Two more things worth knowing. Text it can't read comes back marked [illegible], and an image with no text returns "No text detected in this image." And since every image is shrunk to 1,024 pixels first, very small text can get lost. In an earlier test on a website screenshot, the titles inside tiny thumbnails were skipped until I cropped the image down to that area.
Ask a Question: one fact at a time
Sometimes you don't want a description at all, just one answer: what a label says, or whether something is in the picture.
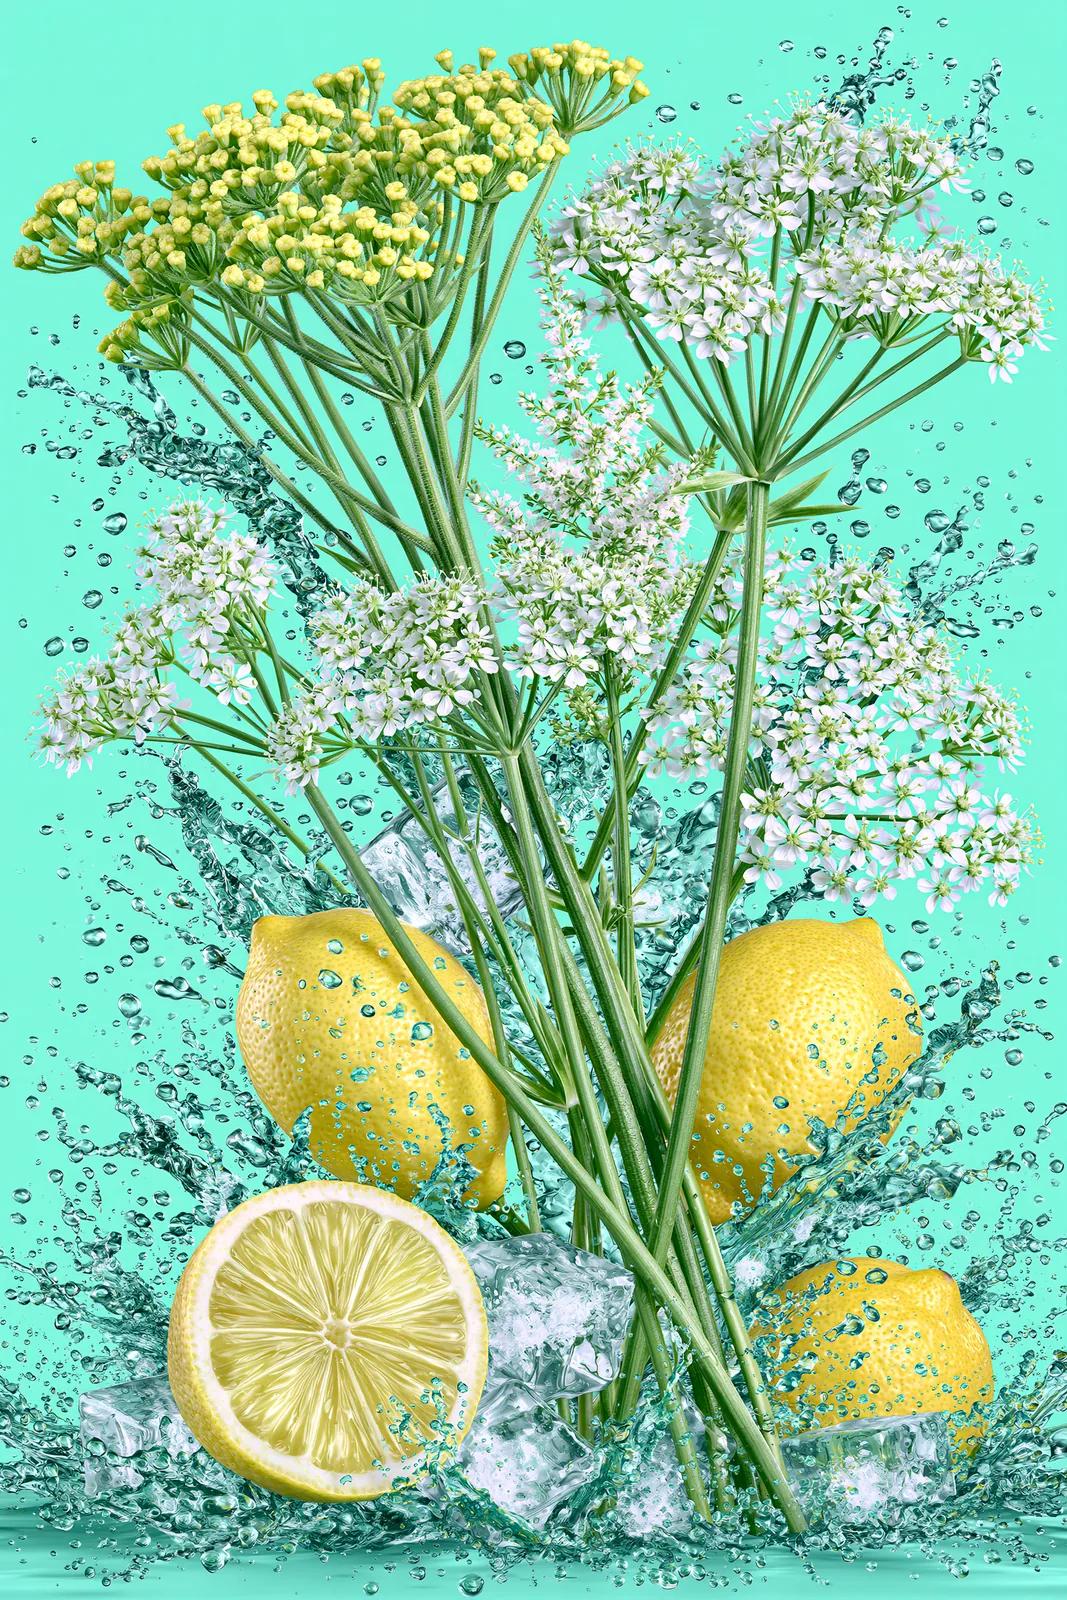
I asked it two questions, one the picture can answer and one it can't.
Output · Ask a QuestionHow many whole lemons are in this image, not counting any lemon that has been cut?
Right. There are three whole lemons, plus one cut in half that the question told it to ignore.
Output · Ask a QuestionWhich country were these lemons grown in?
Also right, and the answer I was hoping for. Nothing in the picture shows where the lemons came from, so it said it couldn't tell and described what it could see rather than making something up.
Counting is where I'd be careful. Three big lemons are easy. In an earlier test, on an image full of overlapping yellow circles, the same kind of question came back with 10, and only two circles were fully visible.
My verdict
Ask a Question works well for single facts you can confirm with a quick look. Questions can be up to 300 characters. If the answer is a count of lots of similar things, count them yourself.
Alt text: when you don't need the describer at all
Back to that batch of product photos. Before you run every one of them through the describer, it's worth knowing that some images shouldn't get a description at all.
Alt text comes from an accessibility rule, WCAG Success Criterion 1.1.1 (opens in a new tab): every image that matters needs a text version that does the same job the image does. Notice it's about the job, not the picture. The W3C's Images Tutorial (opens in a new tab) and its alt text decision tree (opens in a new tab) both start by asking what an image is for. Once you've answered that, you know which mode to use, or whether you need one at all:
| If the image is | The W3C's advice | What to do |
|---|---|---|
| Just decoration, or already explained by the text around it | Leave the alt text empty | Skip the describer and write alt="" |
| Text that isn't repeated anywhere else on the page | Put that text in the alt text | Use Extract Text, then check it |
| Inside a link or a button | Say where the link goes or what the button does | Write it yourself. Describing the picture is the wrong answer here |
| A photo or simple image that adds meaning | A short description that gets that meaning across | Use Describe Briefly, then trim it |
| A chart or a complex diagram | Put the information in the page text | Describe in Detail can draft that page text, but it doesn't belong in the alt text |
If you wanted a prompt, not a description
A description is meant for people to read. If what you really want is text to feed an AI image generator so it can recreate or remix a picture, that's a different job, and there's a separate tool for it.
Turn an image into a prompt insteadTurn any image into an AI promptConclusion
Back to those product photos due tomorrow. You don't have to write every description from scratch. Pick the mode that fits the job, let the describer write the first draft, and spend your time on a quick read of each answer instead. The things I'd look for are guesses, items counted twice, and notes about where things sit.
Try the AI image describer on your own images. You get 8 free descriptions a day without an account, and each one costs 1 credit once you sign in.
Sources
The outside references this article relies on, so you can check them yourself.
5 references
- Gemini 2.5 Flash-LiteGoogle AI for Developers · Updated June 23, 2026
- Gemini deprecationsGoogle AI for Developers · Updated September 5, 2026
- Understanding Success Criterion 1.1.1: Non-text ContentW3C Web Accessibility Initiative · Updated August 10, 2026
- Images TutorialW3C Web Accessibility Initiative · Updated April 8, 2026
- An alt Decision TreeW3C Web Accessibility Initiative · Updated May 13, 2024