

PNG · JPG · WebP
Full breakdown of subject, setting, colors, lighting, mood, and composition
Your description will appear here
Upload an image, pick a mode, and the text renders on this canvas — ready to copy.
Describe this image, describe the picture, or ask anything about it — in detail or briefly, as alt text, a caption or a product listing, identify objects, analyze art style, extract text (OCR), in 19 languages.
Three pictures, three modes, and exactly what the describer wrote for each. Pick one to read it in full.
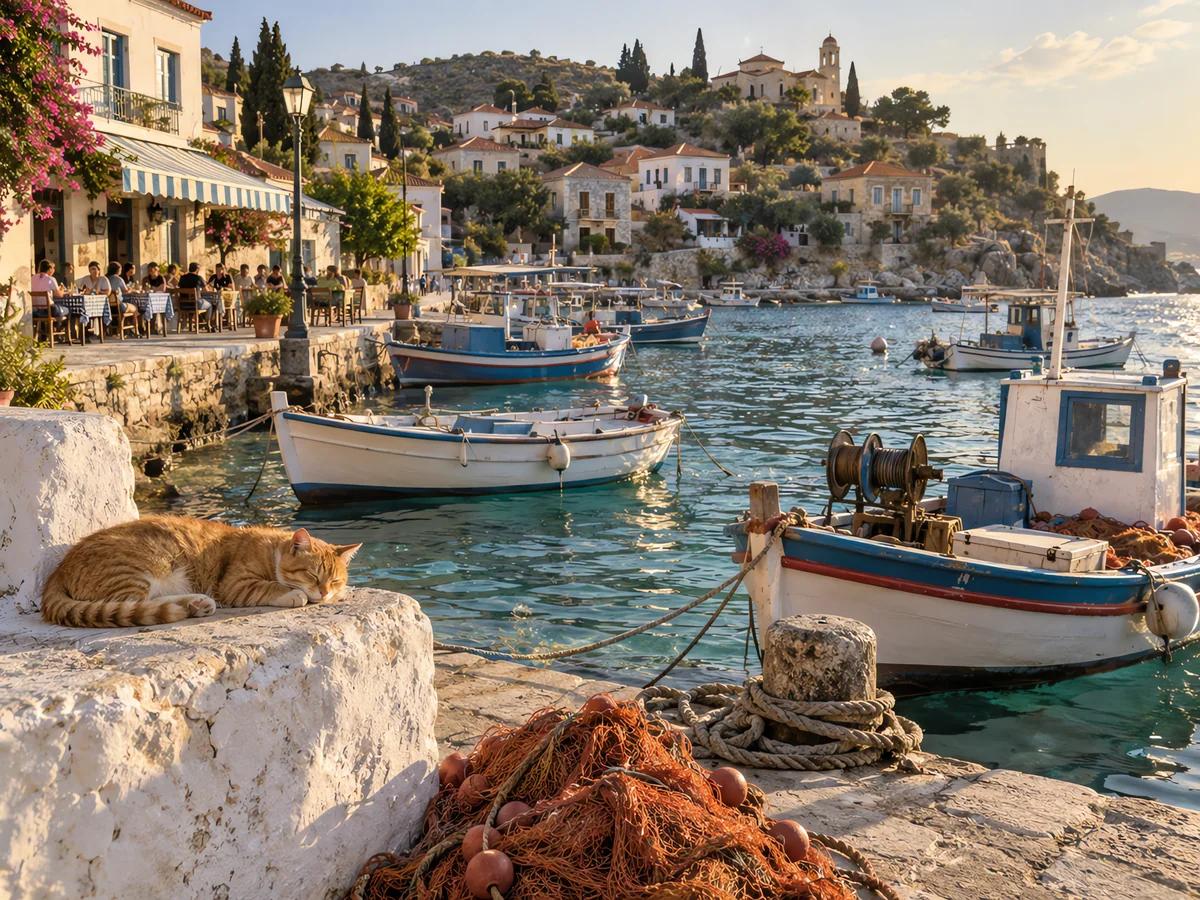
A photograph captures a serene coastal scene in a Mediterranean village. In the foreground, an orange tabby cat is curled up asleep on a rough, white stone ledge, its striped fur catching the warm sunlight. To the right of the cat, a pile of bright orange fishing nets with buoys lies on the stone quay, with thick ropes coiled around a weathered bollard. The water is a clear, shimmering turquoise, reflecting the sky and the boats. Several small fishing boats are moored in the harbor, their hulls painted in shades of white, blue, and red. One boat in the mid-ground is particularly detailed, featuring a winch and various fishing equipment. Further out in the water, more boats are visible, and the sea extends to the horizon. The background is dominated by a hillside covered with traditional white-washed houses with red-tiled roofs, interspersed with olive trees and cypress trees. A church with a bell tower stands prominently on the hill. Along the waterfront to the left, a row of tables and chairs with blue and white striped awnings suggests a cafe or restaurant, where several people are seated, enjoying the view. The lighting indicates it is late afternoon or early evening, with the sun casting long shadows and bathing the scene in a warm, golden glow. The light highlights the textures of the stone, the water, and the cat's fur, while creating a soft, diffused atmosphere. The overall mood is peaceful and idyllic, evoking a sense of tranquility and timelessness. The perspective is from a slightly elevated viewpoint, looking across the harbor towards the village on the hill, with the foreground elements providing a sense of depth and scale.
278 words
Not sure what you're looking at? Upload the picture and the AI image describer tells you what's in it — the subject, the setting, the style, the objects, even the exact text printed inside the image, in any of 19 languages. It works on photos, artwork, screenshots, and scanned documents. Use the description for alt text, captions, cataloging, research, or simply to make sense of an unfamiliar image.
Describe 8 images a day without an account. Signed in, each description is 1 credit.
Beyond fixed descriptions — type any question about your image and get a direct, specific answer.
Your image is analyzed in memory and immediately discarded. Never stored, never used for training.
Pick the mode that matches your task — each one uses a specialized analysis strategy.
A comprehensive breakdown covering the subject, setting, colors, lighting, mood, composition, and fine details. Perfect for long descriptions, archiving, and accessibility.
One or two sentences that capture the essence — ideal for quick cataloging and file naming.
One plain sentence for the alt attribute on a website, blog or CMS: the subject, what it is doing, and any text that matters. No "image of", no filler.
A short caption that fits what the picture shows, with three to five relevant hashtags, ready to post on Instagram, X or a blog.
Turn a product shot into store listing copy: a title, a short description and the key details a buyer checks. It only writes what it can see, never made-up specs.
Detailed, respectful description of appearance, clothing, pose, and expression. Never attempts to identify who the person is.
A grouped inventory of every visible object with color, material, and state — foreground to background, nothing missed.
Medium, technique, art movement, palette, and the artists a work evokes. Great for studying references and building style vocabularies.
Verbatim transcription of every piece of text in the image — signs, labels, documents, screenshots — with location notes.
“How many people are in this photo?” “What breed is the dog?” “What does the sign say?” — switch to question mode and use the AI as your visual assistant. It answers based strictly on what's visible in the picture.
Three steps from picture to text
Drag and drop a PNG, JPG, or WebP file — or paste directly from your clipboard. Photos, artwork, screenshots, and scans all work.
Choose from ten description modes and 19 output languages. Ask a custom question if you need something specific.
Get the result in seconds, copy it with one click, and use it anywhere — alt text, catalogs, captions, or documents.
Everything you need to know about describing images with AI.
Drop the image in and the describer reads it straight away — no button to hunt for, no account. Pick Detailed when you want the full scene (subject, setting, style, mood, notable objects) or Brief when a caption-length line is enough. If you had a specific question in mind, switch to Ask and type it: the describer answers about that picture rather than describing it generically.
An AI image describer is a tool that converts pictures into text. It uses a vision AI model to analyze your uploaded image and explain what it sees — the main subject, setting, colors, objects, artistic style, and even the exact text printed inside the image. It's useful for alt text, accessibility, content cataloging, research, and quickly understanding unfamiliar images.
Upload your image and the describer works as an image description generator, writing a clear, structured description you can use as a caption, alt text, or design annotation. It follows the object–action–context approach recommended for accessible image descriptions — naming the main subject, what's happening, and the surrounding context — so the result reads well for sighted viewers and screen-reader users alike. Pick Alt Text for a one-sentence alt attribute, Detailed for a rich description, or Caption for a short line to post with the picture.
Without an account you can describe 8 images a day for free, no card needed. After that, log in and each description costs 1 credit (refunded if it fails).
Ten modes: Describe in Detail (comprehensive breakdown), Describe Briefly (1-2 sentence summary), Alt Text (one sentence for the alt attribute), Caption (a social post with hashtags), Product Description (store listing copy), Describe the Person (appearance, clothing, pose), Recognize Objects (grouped inventory), Analyze Art Style (medium, technique, influences), Extract Text (verbatim OCR), and Ask a Question (custom visual Q&A).
Yes. Switch to "Ask a Question" mode and type anything — "How many people are in this photo?", "What does the sign say?", "What breed is the dog?" — and the AI answers based strictly on what is visible in the image.
Yes. The Extract Text mode transcribes every piece of visible text verbatim — signs, labels, documents, screenshots, watermarks — preserving spelling and capitalization, with a note about where each text block appears in the image.
19 output languages: English, Spanish, French, German, Italian, Portuguese, Dutch, Polish, Russian, Turkish, Arabic, Japanese, Korean, Chinese (Simplified and Traditional), Thai, Indonesian, Norwegian and Danish. In OCR mode, extracted text always stays in its original language while notes are written in your chosen language.
PNG, JPG and WebP files up to 10MB each, or paste an image straight from your clipboard. Photos, artwork, screenshots and scans all work. Before the AI reads the picture, its longest side is scaled down to 1,024 pixels, which keeps results fast but means very small print in a large photo can get lost.
It is good at the things a person sees first: the subject, the setting, colors, objects, mood and any large, legible text. It is weaker on tiny details, text that is small or partly hidden, and crowded scenes where a person would have to look twice. It answers from what is visible and does not identify who someone is. To get more from a hard picture, crop to the part you care about, use Ask a Question for the one thing you need, or Extract Text for printed words.
Be specific and ask about one thing. "How many people are in this photo?", "What does the sign on the left say?" and "What breed is the dog and roughly how old?" work better than "What is this?". Ask for the format you want ("answer in one sentence", "list the objects as bullet points") and the answer follows it. If the first answer is too general, crop to the area and ask again.
Yes. The text is yours to use for alt text, product listings, catalogs, captions, documents and client work. You are still responsible for checking it before you publish: read it against the picture, and don't present an AI-written description as a statement of fact about a real person or a medical or legal matter.
No. The describer is built for ordinary photos, artwork, screenshots and documents. Our Acceptable Use Policy sets out what is not allowed on Vormly, and a picture that breaks it may be refused.
Image to Prompt produces a generation prompt — text formatted for AI image models like Midjourney or Stable Diffusion to recreate the image. The Image Describer produces human-readable text: descriptions, object lists, OCR transcripts, and answers to questions. Use Describe Image to understand a picture; use Image to Prompt to regenerate one.
No. Your image is analyzed in memory and discarded immediately after the description is generated. It is never saved, shared, or used to train AI models.
Want to recreate the image with AI instead of just describing it? Extract a generation-ready prompt for Midjourney, SD, and GPT Image.
Turn the description into something new — generate optimized prompts for any AI model from a simple idea.

Only care what they're wearing? Get a garment-by-garment breakdown, the named style, and a paragraph ready for a character card.
8 free descriptions a day without signing up — then 1 credit each once you log in.